 Farhan Paal
Before analyzing an algorithm, we need to understand a simple question:
How much work does the algorithm have to do as the input becomes larger?
We usually cannot judge an algorithm simply by running it once. The running time depends on the input, and different inputs can make the same algorithm perform differently.
This is why we analyze an algorithm’s behavior under different cases.
What Is Algorithm Analysis?
Algorithm analysis is the process of studying the resources an algorithm requires as the size of its input increases.
The two main resources are:
- Time: how much computational work the algorithm performs.
- Space: how much additional memory it requires.
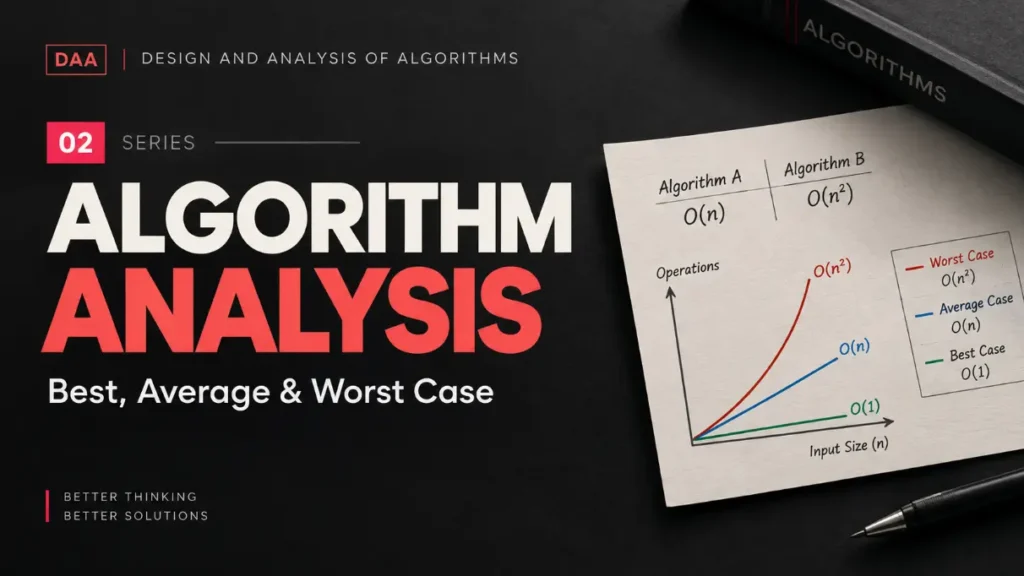
In this article, we will focus mainly on time analysis and the three common cases used to describe an algorithm’s performance:
- Best case
- Average case
- Worst case
Best-Case Analysis
The best case describes the situation in which an algorithm performs the minimum amount of work.
Consider a simple linear search.
Suppose we have: [10, 25, 37, 42, 56] and we want to find 10.
The algorithm checks the first element: 10 = 10
The element is found immediately. So the algorithm performs only one comparison.
This is the best case for linear search.
If the input contains nn elements, the best case requires: 11 comparison.
Therefore, the best-case time complexity is: O(1)
This means the amount of work does not grow with the size of the input in this particular case.
Worst-Case Analysis
The worst case describes the situation in which an algorithm performs the maximum amount of work.
Using the same example: [10, 25, 37, 42, 56]
Suppose we search for 56.
The algorithm has to check: 10 → 25 → 37 → 42 → 56
It needs to examine every element before finding the target. If there are nn elements, the algorithm may need: n comparisons.
Therefore, the worst-case time complexity is: O(n)
The worst case is particularly useful because it gives us an upper bound on how much work the algorithm may need for an input of a given size.
Average-Case Analysis
The average case describes the expected amount of work over a collection of possible inputs.
For linear search, the target might be:
- near the beginning,
- somewhere in the middle,
- near the end.
If the target is equally likely to appear at any position, the average number of comparisons is approximately:
n+12\frac{n+1}{2}
For large nn, this grows proportionally to nn.
Therefore, the average-case complexity is: O(n)
Average-case analysis can be useful, but it often requires assumptions about how likely different inputs are.
A Simple Comparison
For linear search:
| Case | Comparisons | Complexity |
|---|---|---|
| Best case | 11 | O(1)O(1) |
| Average case | Approximately n+12\frac{n+1}{2} | O(n)O(n) |
| Worst case | nn | O(n)O(n) |
The important thing is not just the exact number of comparisons.
We are interested in how the amount of work grows as nn increases.
Why Do We Analyze Different Cases?
Imagine two algorithms that solve the same problem. One algorithm might be extremely fast for a particular input but become slow for another.
Another algorithm might perform consistently regardless of the input. Looking at only one example would not tell us much about their overall behavior.
Best-case, average-case, and worst-case analysis give us different ways to understand this behavior. In practice, worst-case analysis is often especially important because it tells us how much work an algorithm may require in the most demanding valid situation.
Time Complexity Is Not Actual Running Time
There is an important distinction. If we say an algorithm has: O(n)
time complexity, we are not saying that it will take exactly nn seconds or exactly nn operations.
Big-O describes the growth of computational work as the input size increases.
For example, consider: 5n+10
and:100n+50
Both grow proportionally to n.
Therefore, both have: O(n) time complexity.
The constants may affect actual execution time, but asymptotic analysis focuses on how the algorithm scales.
Why Input Size Matters
Consider two algorithms.
Algorithm A performs approximately:
\[
n
\]
operations.
Algorithm B performs approximately:
\[
n^2
\]
operations.
For \(n=10\):
\[
n=10
\]
while:
\[
n^2=100
\]
The difference is already noticeable.
For \(n=1{,}000\):
\[
n=1{,}000
\]
while:
\[
n^2=1{,}000{,}000
\]
As the input becomes larger, the difference becomes much more significant. This is the main reason we study algorithm complexity.
An algorithm that works well for a small input may not scale well to a large one.
What We Learn from Algorithm Analysis
Algorithm analysis helps us answer questions such as:
- How much work does an algorithm perform?
- How does its performance change as the input grows?
- What happens in the best case?
- What happens in the average case?
- What happens in the worst case?
- How much memory does it require?
- Will the algorithm scale to large inputs?
These questions help us compare different approaches to the same problem.
Algorithm analysis is about more than calculating a complexity such as O(n) or O(n^2).
The real goal is to understand how an algorithm behaves as the problem grows.
In the next article, we will look more closely at growth of functions and learn why some complexity classes scale much better than others.